Businesses implementing AI services report up to a 40% reduction in operational costs and a 30% increase in productivity. (Source: GlobussoftAI OpenClaw Services Stats) This beginner guide training sets shows you how better data makes those gains real in 2026. A training set is the data you use to teach a model how to make predictions; you hold back separate data to check your work and to verify final results. If you get the split wrong, your model can look smart on paper and still fail in the field.
Moreover, you don’t need a PhD to get this right. You need clean examples, a fair split, and a simple loop: train, validate, test, repeat. Therefore, we’ll cover what each split means, how to build a solid dataset step by step, the traps to avoid, and tools that save hours. Finally, you’ll leave with a week-one plan you can act on today.
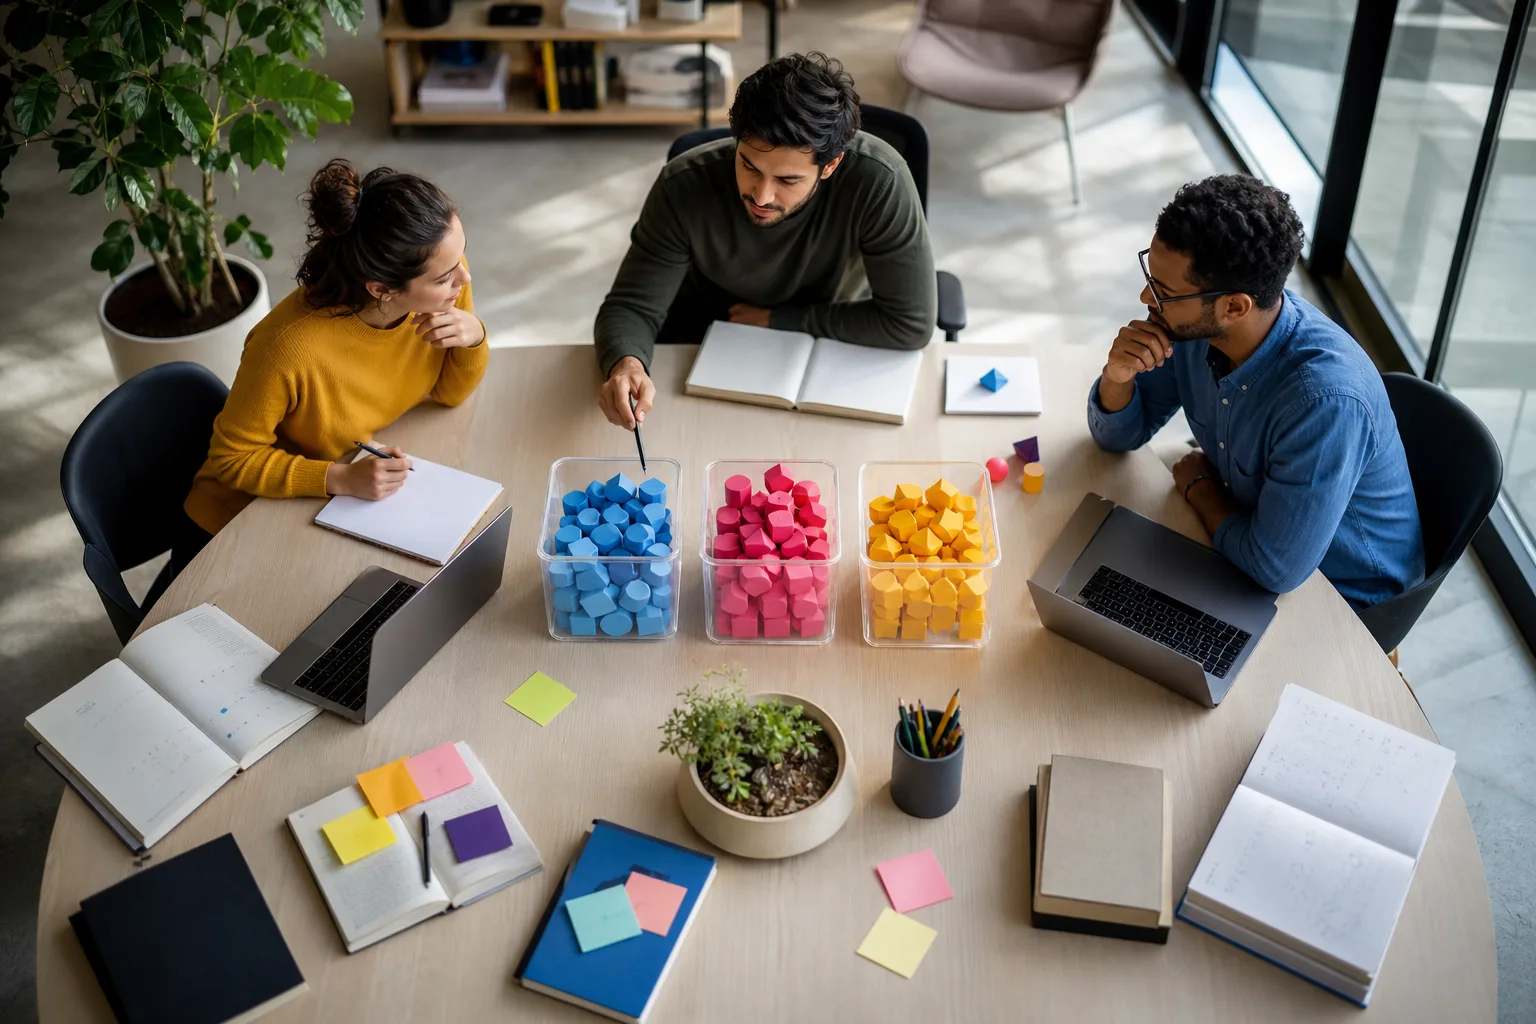 , Validation (15%), Test (15%) with arrows to a model; include flashcard analogy icons; clean 2026 design)
What Is a Training Set and Why Does It Matter?
A training set is the set of labeled examples you feed a model so it can learn patterns. The validation set is a small, separate set you use during training to tune choices like learning rate or prompts. The test set is locked away until the very end to measure true, unbiased performance. For a crisp primer, see Wikipedia’s article on training, validation, and test data sets.
In supervised learning, every example pairs inputs with the correct output (like “email text” → “spam or not”). The model learns by comparing its guess to the label and adjusting. In unsupervised learning, you still use a training set, but labels aren’t present; the model looks for structure, such as clusters in customer behavior.
However, the split is the secret sauce. If the same pattern appears in both training and test because of a leak, your scores lie. As a result, you’ll ship a model that breaks on day one. This is why a disciplined split and careful handling of time, user, and source boundaries matter, even for small projects.
A quick analogy: flashcards for studying
Think of exam prep with flashcards:
- Training set = the flashcards you study with.
- Validation set = the practice quiz you take to see if you should change tactics.
- Test set = the real exam you never peek at in advance.
For example, if you slip a few flashcards from your study pile into your exam, you’ll score higher than you deserve. That’s data leakage in daily life. Therefore, the beginner guide training sets mindset is simple: practice on one pile, tune your plan on another, and prove it on a final, clean exam.
How to Build a High-Quality Training Set: Step by Step
Great models start with great data. Follow these six steps and you’ll avoid 80% of rework later. Moreover, this flow works whether you’re training classic classifiers or fine-tuning modern LLMs on domain-specific data.
-
Define the problem: Be precise. Are you classifying support emails into “billing,” “tech,” and “shipping”? What metric will you track (F1, accuracy, recall)? How will you use the model in 2026 production? Write these as acceptance criteria.
-
Collect raw data: Pull from diverse sources: product logs, tickets, forms, and public datasets. However, keep consent and compliance in mind. Therefore, store provenance (where each record came from) so you can audit and filter later. 3) Clean and preprocess: Remove duplicates, fix encoding, normalize units, and standardize formats. For text, strip boilerplate signatures.
For images, unify sizes and color modes. As a result, the model sees signal, not noise. 4) Label or annotate: Create a clear guide with examples and edge cases. In addition, run a pilot with 50–100 items to measure agreement between annotators. If people disagree, the model will too.
Therefore, refine the guide before full-scale labeling. 5) Split data (70/15/15): Use about 70% for training, 15% for validation, and 15% for test. Furthermore, stratify by class so each split reflects the true mix. If time matters (like forecasts), split by date so future data stays in validation and test. 6) Validate for bias and balance: Check whether the dataset over-represents a user group, region, or device.
For example, if 90% of your speech data is from one accent, your results will skew. Therefore, rebalance or collect more samples before training.
“Clean labels, fair splits, and repeatable steps beat clever tricks. Start small, then scale.”
Visualizing the pipeline
 → Train/Validate → Test/Deploy; modern flat icons; legible labels)
Keep your loop tight
Train a baseline model fast, note where it fails, then go fix the data. Tools for versioning data (like DVC) and prompt or hyperparameter tracking keep results repeatable. In addition, if you’re fine-tuning on domain-specific data, log each dataset version that feeds a new run so you can trace gains to the exact changes you made.
Therefore, treat your dataset like code. Version it, review it, and require approvals for changes. Finally, revisit this beginner guide training sets checklist each time you open a new labeling sprint.
Start a free data audit today →
Also Read!
A Beginner’s Guide to H2O Machine Learning
How to Get Started with AI Deep Learning Implementation for Your Business
5 Common Training Set Mistakes That Wreck Your Model
Even pros get tripped up by the same five issues. Fortunately, each has a clear fix. For a second perspective on splits and evaluation, compare with Google’s ML Crash Course on training and test sets.
1) Data leakage
Leakage is when information from the future or from the label sneaks into training features. For example, a churn model that includes “was_refunded” from a month later will boast 99% accuracy on test. However, it will fail on real-time data. Fix it by removing post-outcome features and by splitting by time or user, not at random.
2) Class imbalance
If only 3% of transactions are fraud, a “predict not fraud” model scores 97% and helps no one. As a result, recall tanks for the rare class. Balance with targeted sampling, class weights, or collecting more positive examples. In addition, report class-wise metrics, not just a single accuracy.
3) Insufficient size
A training set with 200 reviews for five classes means each class gets 40 examples. That’s thin. Therefore, the model will overfit, then underperform on live data. Start smaller in scope (fewer classes) or grow the dataset. Moreover, focus on hard cases the model misses.
4) Label noise
Inconsistent labels teach the model to guess randomly. For example, five annotators mark “password reset” as both “billing” and “tech.” Fix this by writing a strict label guide, running adjudication on disagreements, and tracking inter-annotator agreement. Therefore, you’ll raise the ceiling on model quality.
5) Overfitting to the training set
If validation loss rises while training loss falls, you’re memorizing. For example, your image model nails the same warehouse background but fails on a new site. Add regularization, augment data, and stop early based on validation. Finally, lock the test set and use it once, at the end.
Moreover, keep a mistake log. When a model fails, trace the error to data, labels, or code. Then add a rule to prevent that error next time. Therefore, your beginner guide training sets process gets sharper with each release.
Tools and Resources for Managing Training Data
You don’t need to build the stack from scratch. Instead, pick tools that save time and make results repeatable.
- Labeling: Label Studio supports text, image, and audio with custom templates.
- Versioning: DVC treats data like code, so you can branch, diff, and roll back.
- Curated corpora: Hugging Face Datasets offers ready-to-use loaders and splits.
- Managed labeling: AWS SageMaker Ground Truth handles workforce and quality checks.
Moreover, services like GlobussoftAI OpenClaw Services are one option if you want managed AI/ML pipeline development for scalable deployment and model training on domain-specific data. As a result, teams get enterprise-grade deployment standards with security-focused setup, including end-to-end encryption and role-based access controls for access. In addition, the framework runs on a self-hosted server and integrates with CRMs and analytics tools to fit into your stack.
Social proof: Reached 100,000 GitHub stars in under eight weeks, with over 1,000 hours of testing data used to explore OpenClaw’s features. (Source: OpenClaw Stats)
Quick view of where each tool helps
| Need | Tool | Why it helps |
|---|---|---|
| Label images/text | Label Studio | Fast setup, custom templates, review queues |
| Track dataset versions | DVC | Reproducible experiments, shareable remotes |
| Load public datasets | Hugging Face Datasets | One-liners to filter, split, and stream |
| At-scale labeling | AWS SageMaker Ground Truth | Managed workforce, quality audits |
Finally, pick a minimal set and write them into your playbook. Therefore, your beginner guide training sets workflow will be easy to teach to new teammates.
Also Read!
What to Do Next: Putting Your Training Set to Work
Start small, ship a baseline, and make the data better each week. You’ll learn faster than waiting months for a “perfect” corpus.
- First, assemble a 1,000–2,000 item labeled set that reflects your real use case.
- Second, split 70/15/15 with stratification or time-aware rules.
- Third, train a simple model and log baseline metrics and failure cases.
- Fourth, fix two top failure modes by adding targeted examples.
- Fifth, retrain, compare runs, and promote only if metrics improve on validation and test.
- Sixth, repeat this loop for three cycles before you scale.
Moreover, track drift after you launch. If users change behavior in 2026, plan a quarterly review to re-label fresh data and re-run the loop. In addition, automate checks: no duplicates, no future leakage, and class balance within set bounds. Therefore, you reduce regressions before they hit customers.
Finally, add a calendar reminder for your data health check. A steady beginner guide training sets habit beats big one-off rebuilds.
Key Takeaways
You covered a lot. Here’s the short list to keep near your desk, with the points that move results the most.
- A training set teaches; a validation set tunes; a test set verifies once. Keep the test set sealed.
- Use a 70/15/15 split, stratified or time-aware. Document the rule in your repo.
- Fix data first. Clean labels and fair class balance raise your quality ceiling.
- Watch for leaks. Remove post-outcome or user-overlapping features before you train.
- Improve in loops. Add targeted hard examples, retrain, and compare runs before deploy.
Moreover, tools like Label Studio, DVC, and curated datasets help you move faster with less guesswork. In addition, managed services can connect the dots from data to production with security and scale baked in. Therefore, if a result doesn’t reproduce on the same data, treat it as a bug. Your 2026 plan should make wins repeatable, not lucky.
Finally, remember the core promise of this beginner guide training sets: clean data, clear splits, and steady iteration beat clever hacks every single time.
What to Do This Week
Day 1: Write a one-page brief with problem, users, metric, and the decision your model will inform. Keep it in your repo. Day 2: Pull a raw sample (5,000–10,000 rows or 500–1,000 images). Remove duplicates and obvious junk. Day 3: Draft a labeling guide with 10 positive and 10 negative examples per class.
Run a 100-item pilot and revise
Day 4: Label to 1,500 items. Then split 70/15/15 with stratification or a time cut. Day 5: Train a baseline, log metrics, find top five failure modes, and plan the next data sprint.
Moreover, schedule a 30-minute review with your team to sign off splits and metrics. In addition, add checks to block data leakage and imbalance in your CI. Therefore, by Friday, you’ll have proof you can move from idea to a model with real numbers. Keep going next week: add targeted hard cases, retrain, and promote only if validation and test both rise.
Finally, if you want a second set of eyes on your plan, bring your brief and a sample to a quick session.