Businesses implementing AI services report up to a 40% reduction in operational costs and 30% increase in productivity (GlobussoftAI OpenClaw program data). This beginner guide feature engineering will show you how to get those gains by fixing the inputs, not by chasing the newest model.
Feature engineering is the craft of turning messy raw data into clear signals your model can use. With strong features, a basic model can beat a fancy one with weak inputs. In 2026, with easy access to high-capacity models, this is the edge that still moves the needle.
I learned this the hard way. I once added a deep model to “save” a weak churn predictor. It failed. Then I added two simple features that captured product usage in the last 7 days and seasonality by month. The old logistic regression won by a mile.
What Is Feature Engineering and Why Does It Matter More Than Your Model Choice?
Feature engineering means turning raw inputs into useful numbers or categories that highlight the signal your model needs. Raw data is messy: missing values, odd scales, booleans as strings, and dates you can’t compare. You fix that by creating features that reflect the rules of your world.
For example, say you predict house prices. Raw columns might include address, square feet, bedrooms, year built, last remodel date, and text notes from the agent. On their own, they are hard to learn from. Instead, you create “price_per_sqft”, “age_of_home”, “years_since_remodel”, “bed_per_sqft”, and “distance_to_city_center”. Each one points the model toward patterns appraisers care about.
Moreover, strong features let simple machine learning models shine. A linear model with “price_per_sqft” and “age_of_home” can beat a deep tree that only sees raw fields. As a result, you move faster and avoid overfitting. This matters not only for models but for predictive analytics platforms where clean, stable features make deployment and monitoring sane.
A Tiny, Concrete Example
- Raw: “1,850 sqft, built 1995, remodeled 2019, 3 beds, $520,000 price”.
- Engineered:
price_per_sqft = 520000 / 1850home_age = 2026 - 1995years_since_remodel = 2026 - 2019beds_per_1000sqft = 3 / (1850/1000)
“Better signals beat bigger models.” I’ve shipped models where two features raised validation scores more than swapping to a new algorithm.
Finally, keep this simple rule: if a human expert would look at a ratio, difference, or trend to decide, encode that judgment as a feature. Your model will thank you later. This is the heart of a practical beginner guide feature engineering mindset.
A Step-by-Step Feature Engineering Framework You Can Follow Today
You can follow these six steps today. I use this in real projects, from small prototypes to AI/ML pipeline development for scalable deployment.
Step 1: Understand the Problem Domain
Talk to a subject expert. Ask what drives the outcome. For house prices, they might say location, size, and condition. For churn, they might say “usage drop before cancel”.
- Write a short “data story”: who, what, when, where, why.
- List 5-10 suspected drivers. These seed your features.
- Define success: metric, baseline, and “good enough” target.
Step 2: Explore and Clean the Raw Data
Profile the data types, ranges, and gaps. Fill missing values in a way that preserves truth.
- Numeric: impute
medianor addis_missingflags. - Categorical: impute with
'Unknown'or most frequent. - Dates: convert to datetime and check timezone drift.
- Text: strip spaces, standardize case.
Small pseudoexamples:
- Missing flags: `df['age_is_missing'] = df['age'].isna.
- Median fill: `df['income_filled'] = df['income'].
Step 3: Create New Features
This is where you add signal. Use binning, encoding, interactions, and date extraction.
- Binning: `df['age_bin'] = pd.
- One-hot encode: `pd.
- Interactions:
df['price_per_sqft'] = df['price'] / df['sqft'] - Dates: `df['days_since_signup'] = (today – df['signup_date']).dt.
- Rolling stats (time series): `df['7d_avg'] = df['events'].rolling(7).
Step 4: Transform Features
Scale and tame skew so your model trains well.
- Standardize: `z = (x – x.mean) / x.
- Log transform skew: `x_log = np.
- Clip outliers: `x_clip = x.
Step 5: Select Features
Cut noise. Keep features that lift signal.
- Correlation screen: drop one of two features with |r| > 0.9.
- Model-based selection: fit a simple tree or L1-regularized model and keep high-importance features.
- Permutation importance: shuffle one feature at a time and measure drop in validation metric.
Pseudo:
selected = [f for f in feats if perm_importance[f] > 0]
Step 6: Validate with Cross-Validation
Lock in gains with honest tests. Use k-fold cross-validation, keep the pipeline consistent, and track the metric you care about.
- K-fold:
K=5; report mean and standard deviation. - Time series: use forward-chaining splits.
- Early stop if gains stall for 2-3 rounds.
Furthermore, link your steps into one repeatable path. For Python, a pipeline ensures the same clean/transform steps hit train and test in the right order. This helps with model training and fine-tuning on domain-specific data later.
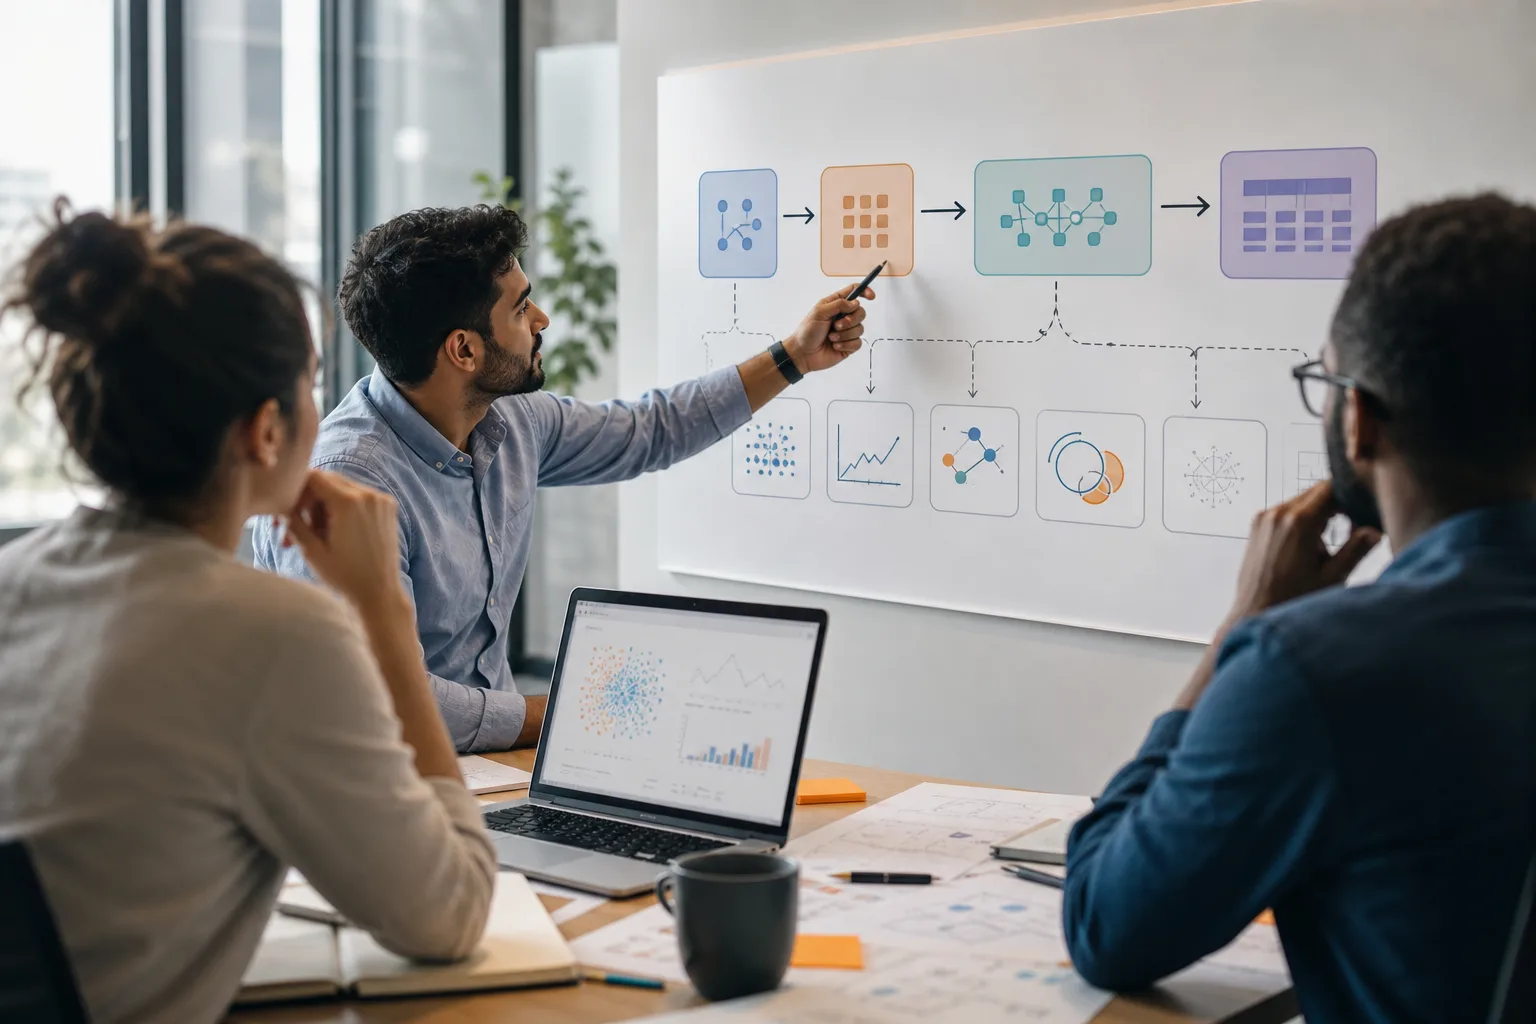 understand domain, 2) explore/clean, 3) create features, 4) transform, 5) select, 6) validate; arrows show data flow; light code snippets near each step)
Quick Reference Snippets
- Train/test split before transforms:
X_train, X_test = split(X, y, stratify=y) - Fit scaler on train only: `scaler.fit(X_train); X_test_s = scaler.
- Save feature list: `feature_names = X_train.columns.
Also Read!
5 Common Feature Engineering Mistakes That Silently Hurt Your Models
First, data leakage. Leakage happens when a feature includes target hints from the future or from labels. For example, “days_until_cancel” used to predict churn at signup. Fix it by building features from data available at prediction time only, and use strict train/validation splits.
Second, ignoring domain knowledge. I once skipped “number of units in building” for rent price because the field was messy. The model missed a key factor. Fix it by asking experts up front and by forcing yourself to encode their top five drivers as features.
Third, over-engineering. It’s easy to add 500 features and feel smart. But you inflate overfitting and training time.
Fix it by pruning hard: use correlation checks and model-based importance. Keep a scoreboard. If a feature does not lift validation by a real margin, drop it.
Fourth, creating features before handling missing values. For instance, you divide price by square feet and get NaNs for missing sqft. That breaks downstream steps. Fix it by imputing first, creating missing flags, and only then building ratios and interactions.
Fifth, applying transforms before the train/test split. I’ve seen scalers fit on all data and bleed test set stats into train. The score looks great until you deploy. Fix it with a pipeline where the split happens first, and every fit step only sees the training fold.
“Split first, fit second.” If you remember one rule from this beginner guide feature engineering path, make it this one.
Additionally, write down each choice in a simple changelog. As a result, you can roll back a bad idea in minutes instead of hours.
Tools and Resources for simplifying Feature Engineering
You don’t need to build everything from scratch. Here are tools that save time without turning your process into a black box.
- Featuretools: open-source, great for automated feature synthesis on relational data.
- scikit-learn pipelines: keep your transforms and models in one repeatable chain.
- Pandas Profiling (ydata-profiling): fast data reports to spot types, skew, and gaps.
- tsfresh: a strong pick for time series features with hundreds of built-ins.
For background reading, the Feature engineering overview on Wikipedia is a short, neutral primer. After that, try tutorials from university courses (e.g., CS classes on *.edu sites) to see hands-on examples.
Moreover, AutoML systems can generate baseline features. Use them to start, not to finish. Inspect what they create, prune, and add domain-driven signals that a template will miss.
As of 2026, teams also need the path from notebook to production. That’s where AI deployment services like GlobussoftAI’s OpenClaw can help you operationalize ML pipelines with feature engineering at scale. The service focuses on AI/ML pipeline development for scalable deployment, AI/ML consulting to build roadmaps and implement solutions, and smooth integration services to fit AI solutions into existing systems.
For security in business settings, OpenClaw emphasizes end-to-end encryption and role-based access controls for security. For cost control, the core framework is free, with a typical VPS around $5/month and total costs usually under $10/month with AI model usage. For social proof, the framework reached 100,000 GitHub stars in under eight weeks and was explored with over 1,000 hours of testing data.
Finally, document your feature build with clear names and comments. Future you (or Ops) will need to trace an outage to the right step fast.
Where These Tools Fit in the Flow
- Profiling during Step 2 (explore/clean)
- Featuretools/tsfresh during Step 3 (create features)
- scikit-learn pipelines during Steps 4–6 (transform, select, validate)
What to Do Next: Putting Feature Engineering Into Practice
Pick one public dataset. Kaggle has many. Choose a task you care about, like predicting rental price, sales next month, or time to failure. Set a three-hour timer to apply the framework you saw above.
First, define your target and metric. Second, do a fast profile and fix missing values. Third, make 5–10 domain-driven features.
Fourth, scale and log-transform where it helps. Fifth, prune with a quick importance check. Sixth, cross-validate and write down the score.
Next, iterate. In round two, add one ratio, one date-derived feature, and one interaction you think matters. In round three, drop the bottom three features by importance. Track scores after each round. As a result, you’ll build a feel for which ideas pay off.
Moreover, share your notebook with a peer and ask which three features they would add. Fresh eyes spot oversights fast. Above all, keep your changes small and measured so you can see what caused a gain or a dip.
Finally, remember that this is a skill built with reps, not memorization. By shipping a small project end to end, you gain more than a week of passive reading.
Start a free planning session →
Key Takeaways
- Strong features beat fancy models with weak inputs; build signals that reflect how experts decide.
- Follow six steps: understand, clean, create, transform, select, and validate with proper splits.
- Avoid silent traps: leakage, ignoring domain clues, over-engineering, missing-value traps, and pre-split transforms.
- Use open-source tools and, if needed, services to move from notebook to production safely in 2026.
- Treat this beginner guide feature engineering process as a repeatable habit: small changes, tested and logged.
What to Do This Week
Pick one dataset, write a one-page “data story”, and run the six-step framework twice. Ship a short report with your best three features, your cross-validation score, and one chart. Then, plan one improvement for next week and queue it up.
Get free deployment consult today →
As a final note: if you want a single sentence to cite, here it is. Feature engineering turns raw, messy inputs into clear signals, and with honest validation and a modest set of domain-driven features, you can raise accuracy faster than by swapping algorithms.