Get a free study design checklist →
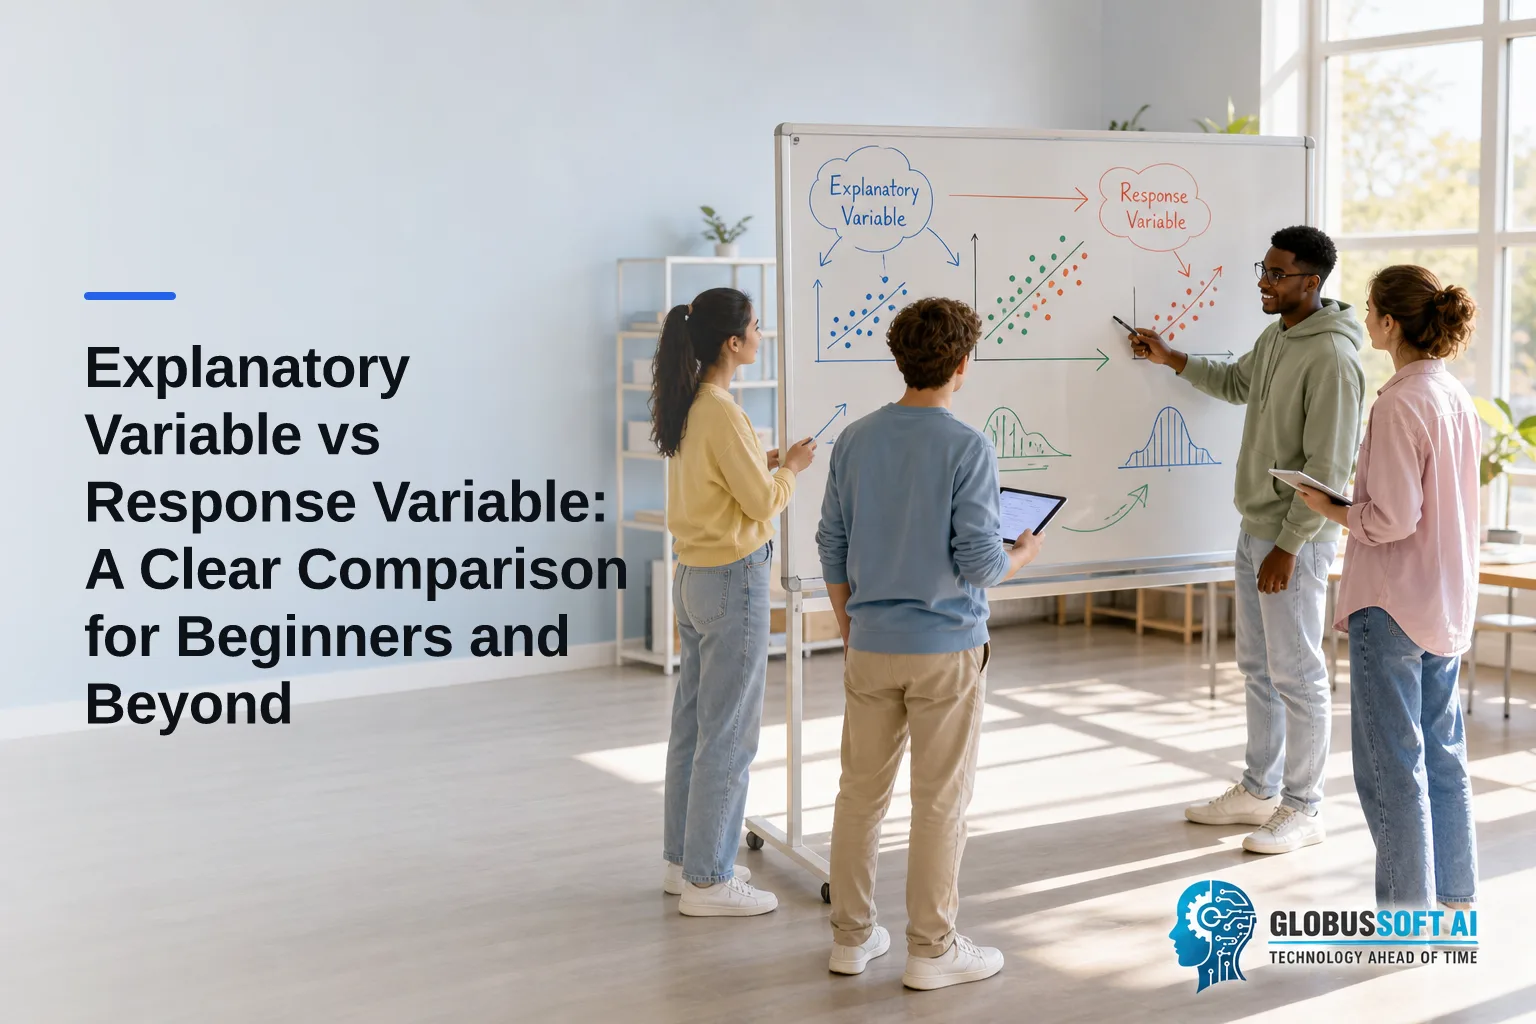
Mislabel one variable, and your conclusion can flip from “works” to “fails.” For beginners and beyond, the short answer is this: the explanatory variable is what you think drives change, and the response variable is what you measure to see that change. In 2026, this clear split still guides sound study design, clean analysis, and valid claims in research and machine learning alike.
 ” and “Response (Y)” with simple arrows from X to Y, overlaid on a scatter plot with X on the horizontal axis and Y on the vertical axis; color palette: navy, teal, white; minimal icons for “manipulate/observe” vs “measure outcome”)
What You Need to Understand Before Comparing These Two Variable Types
A study stands on a simple idea: cause and effect. The explanatory variable (the suspected cause) aims to explain or predict changes. The response variable (the effect) records the result. If you keep this frame in mind, you’ll avoid most mix-ups that trap beginners and beyond.
However, the map is not the territory. You can name a variable “explanatory,” yet the real world may hide other forces. Therefore, good design asks: How will you vary or observe the explanatory variable? How will you measure the response? And what could be nudging both in the background?
For example, suppose you test whether a 100 mg dose of a drug lowers blood pressure more than 50 mg. Here, dose is explanatory, and blood pressure change is the response. As a result, you can write a clear hypothesis, choose the right test, and plot the data with the dose on the x-axis and pressure on the y-axis.
For Beginners and Beyond: Cause-and-Effect Starter Checks
- Ask what you plan to change or observe first.
- Then state what you plan to measure as the outcome.
- Finally, note at least one other factor that could influence both.
In short, label the “driver” as explanatory and the “measured result” as the response. This labels your axes, directs your analysis, and keeps your claims grounded in 2026 standards of clear scientific reasoning.
Explanatory Variable: Definition, Role, and Real-World Examples
The explanatory variable, also called the independent or predictor variable, is the input you believe explains or predicts the outcome. You may manipulate it in an experiment (e.g., assign a dose) or simply observe it in a study (e.g., record daily steps). In either case, it sits on the “from” side of your question: from what are you predicting?
This framing helps you write tight hypotheses. For instance, “Increasing weekly study hours (explanatory) raises final exam scores (response).” Moreover, it makes your graphs clearer: in a scatter plot, put the explanatory variable on the x-axis to show how the outcome responds as x changes.
However, the label “explanatory” does not prove cause. If you do not control the input or randomize groups, other variables may still drive the effect. Therefore, use the term as a claim to test, not as proof that you found the cause.
For Beginners and Beyond: Spotting Predictors in Practice
- Education research: Weekly study hours as the predictor of final exam score.
- Public health: Daily cigarette count predicting lung function score.
- Digital ads: Campaign spend in USD predicting click-through rate.
- Sports science: Training volume (miles per week) predicting 10K race time.
In each case, you look to the explanatory variable for shifts that may map to the outcome. You can change it by design (e.g., assign 5, 10, or 15 study hours) or observe it as is (e.g., track ad spend over 12 weeks). Either way, you use it to explain or predict.
Response Variable: Definition, Role, and Real-World Examples
The response variable, also called the dependent or outcome variable, is the measured result. It answers the “what happened?” part of your study. You collect it after you set or observe the explanatory variable, and you test whether changes in the input match changes in this outcome.
This variable has a key strength: it ties your study to real, measured effects. Scores, rates, times, and biomarker levels are all common examples. In addition, having a well-defined response variable improves power, reduces noise, and makes your results easier to judge.
On the other hand, response variables can be influenced by confounders, unmeasured factors that affect both the input and the outcome. Therefore, you must plan for them: restrict the sample, randomize, match groups, or adjust in the analysis.
For Beginners and Beyond: Matching Outcomes to Inputs
- Education research: Final exam score as the outcome of study hours.
- Public health: FEV1 lung function score as the outcome of daily cigarettes.
- Digital ads: Click-through rate (percentage) as the outcome of ad spend.
- Sports science: 10K finish time (minutes: seconds) as the outcome of training volume.
In each pair, the response variable is the numerical or categorical result you measure to test your hypothesis. It belongs on the y-axis in a scatter plot, where you can see how it changes across the x-axis values.
Also Read!
What Is an Explanatory Variable? A Beginner’s Guide
How to Set Up a WhatsApp AI Automation Bot for Your Ecommerce Store
Side-by-Side Comparison: Explanatory vs Response Variable Across Key Dimensions
It helps to compare the two variable types head to head. The table below anchors the most-used terms and where these variables live in models and graphs, clarity that benefits beginners and beyond.
| Dimension | Explanatory Variable | Response Variable |
|---|---|---|
| Core definition | The input you think explains or predicts | The measured outcome that may change |
| Alternate names | Independent, predictor, feature (X) | Dependent, outcome, target (Y) |
| Role in hypothesis | “If X increases/decreases/changes…” | “…then Y will rise/fall/differ.” |
| Who controls it? | You may manipulate or just observe it | You measure it after X is set/observed |
| Placement on graphs | x-axis in scatter/line plots | y-axis in scatter/line plots |
| In experiments | Assigned by design (e.g., dose levels) | Measured effect (e.g., blood pressure change) |
| In observational studies | Recorded as-is (e.g., steps per day) | Recorded as-is (e.g., BMI) |
| In ML terms | Features (X matrix) | Target (y vector) |
| Typical examples | Study hours, ad spend, dose, training volume | Exam score, CTR, systolic BP, race time |
Specifically, in scatter plots, the explanatory variable goes on the x-axis and the response on the y-axis. Furthermore, the explanatory may be manipulated in experiments or simply observed in surveys and logs, while the response is measured as the outcome of interest.
 ” on the x-axis and Y labeled “Response (Exam Score)” on the y-axis; right panel shows a simple bar chart contrasting experimental groups with different doses and their mean outcomes; minimal gridlines, high contrast labels)
“Label X as what you change or observe first; label Y as what you measure as a result.” — A rule of thumb that saves hours of rework
Therefore, once you know which side of the question a variable sits on, input or outcome, you know how to write your model, place your axes, and choose the right test.
Download the free variable guide →
When the Distinction Gets Tricky: Observational Studies, Correlation, and Common Mistakes
Real data can blur clean labels. In observational studies, you do not assign the explanatory variable; you only observe it. As a result, factors like age, income, or baseline health may influence both the input and the outcome. For background, see Observational study.
Moreover, bidirectional relationships exist. For example, stress may affect sleep, and poor sleep may increase stress. In such cases, a time-based design (e.g., a lag model) or an experiment is needed to learn direction. Otherwise, a label like “explanatory” is tentative.
In addition, lurking variables and confounders can mimic cause and effect. For instance, ice cream sales and sunburn rates both rise in summer; temperature is the lurking driver. To read more, see Confounding. Therefore, do not claim causation from correlation alone. Randomization, controls, and pre-registered plans help protect your claims.
For Beginners and Beyond: Pitfalls to Avoid
- Treating “explanatory” as proof of cause without randomization.
- Swapping axes in a scatter plot and misreading the slope.
- Ignoring time order when effects may lag inputs.
- Forgetting confounders that move both X and Y.
Finally, correct variable setup pays off outside the classroom. Businesses implementing AI services report up to a 40% reduction in operational costs and 30% increase in productivity. Clear X/Y assignment is one reason models stay stable, reproducible, and useful at scale. And when you work with data, choose tools that protect privacy, end-to-end encryption and role-based access controls help keep research data safe while you explore results.
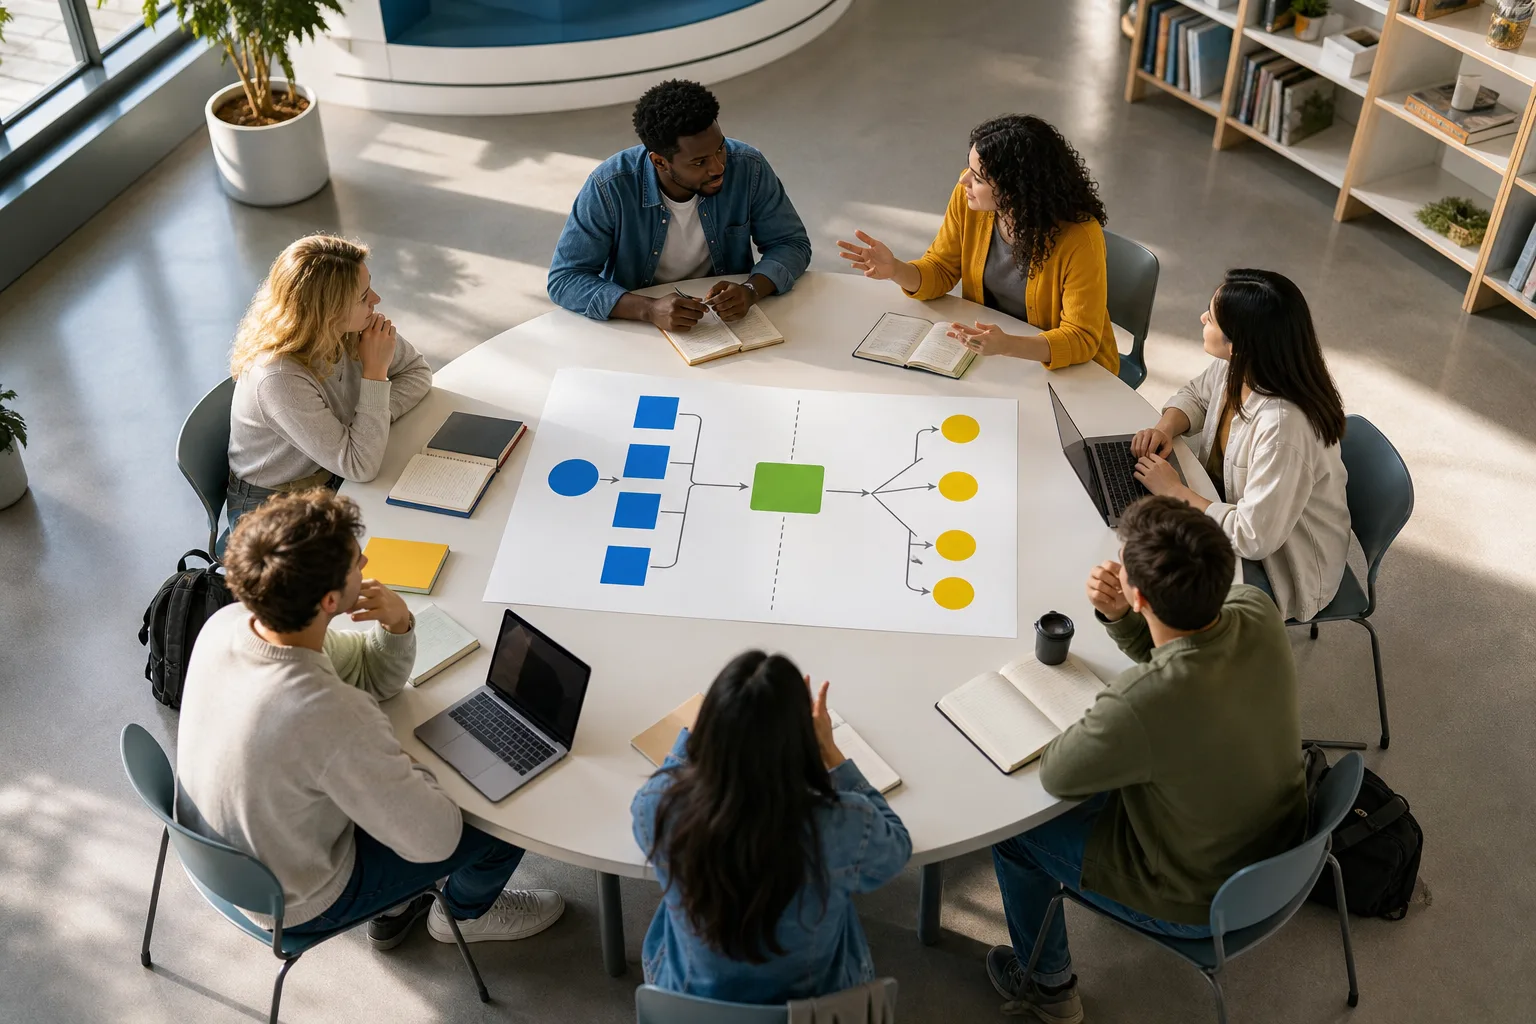 ” vs “Observational (observe X)” leading to “Measure Y” with branches for “Confounders?” and “Randomize/Adjust”; friendly icons for clipboard, stopwatch, and shield to suggest planning, timing, and security)
Verdict: How to Always Identify the Right Variable in Your Analysis
Here is a fast way to label variables that serves beginners and beyond. First, ask, “What am I changing or predicting from?” That is your explanatory variable. Second, ask, “What am I measuring as a result?” That is your response variable. Third, place the explanatory on the x-axis and the response on the y-axis whenever you draw a scatter plot.
Therefore, write your hypothesis in two parts: “If [explanatory] changes, then [response] will change.” Next, check time order and study type. In experiments, you control the input; in observational work, you watch it and adjust for confounders. In predictive analytics platforms, correctly assigning explanatory and response variables is the foundation of any machine learning model. In 2026, that small, early choice still shapes the truth you can claim later.
Quick Decision Guide (For Beginners and Beyond)
- Label as explanatory if it is the input you set or the factor you use to predict from.
- Label as response if it is the outcome you record, score, or rate after observing or setting the input.
- In tools, map features to X and your single target to y; if you need expert help turning that plan into a stable pipeline, GlobussoftAI OpenClaw Services can configure and support it for business use.
Book a quick consult, free today →
To wrap up, keep it simple under pressure: X is what you change or observe first; Y is what you measure next. Use that rule to write strong hypotheses, build clean charts, choose sound tests, and make claims you can stand by.