Forty percent lower costs and a 30% productivity boost are real for teams that add AI services. That upside is reachable with self-hosted ai agent deployment if you plan for security, data residency, and live risk. Here’s the short answer: pick infra you control, choose an agent framework, lock it down with end-to-end encryption and role-based access controls, wire it to core systems, add monitoring, and load test it before you touch live funds.
As a fintech engineer, you work under audit clocks and fraud SLAs. In 2026, you can run agents on your own metal or private cloud with tight data controls, and still keep inference latency under your fraud window. This guide shows the exact setup that holds up in SOC 2 and PCI-DSS audits, with simple choices you can make this week.
If you want a quick primer on architectures and roles before you start, skim this short overview on agent types
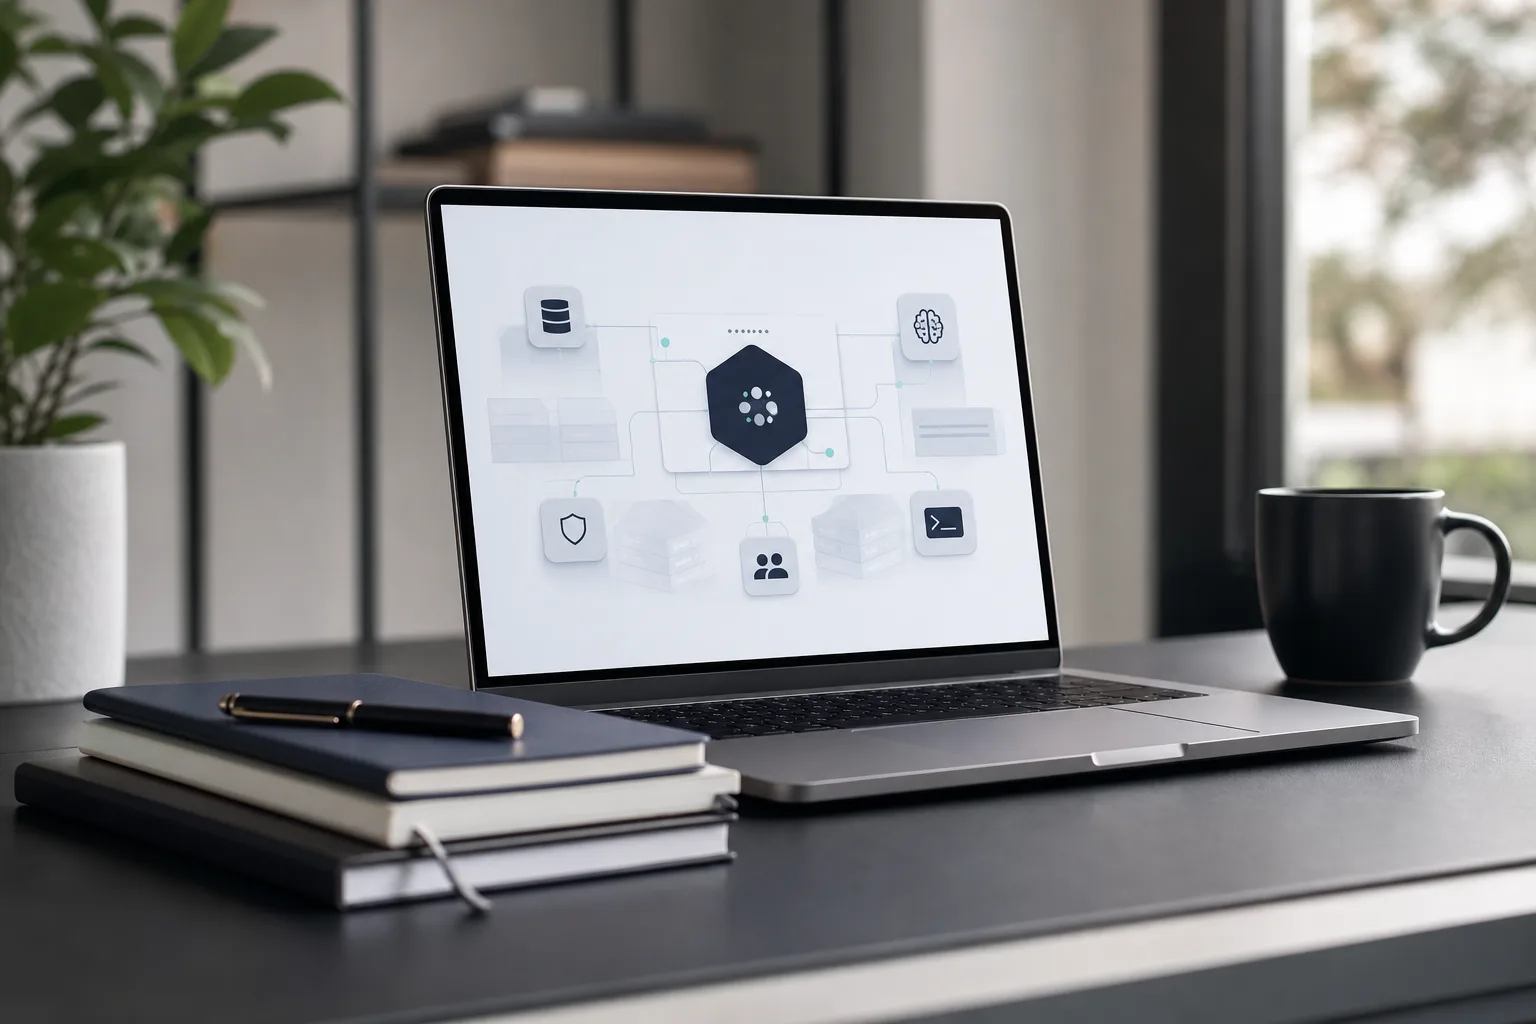 , data layer (transaction DB, feature store), monitoring/alerting, and audit logging; color-coded lines for data in motion and at rest; 2026 label in corner)
Why Fintech Teams Self-Host AI Agents (And When It Actually Makes Sense)
You self-host when data control and timing risk are non-negotiable. If your agent touches PAN data, PII, or trading signals, keeping raw tokens inside your network and encrypting them end-to-end reduces breach blast radius and meets board-level risk appetite. End-to-end encryption and role-based access controls are not “nice to have” in finance; they are table stakes that your internal security review will check first.
For compliance, your control plane should map to SOC 2 controls and PCI-DSS scope. Audit logging, key rotation, and least-privilege roles cut review time and cost. For cross-border flows, self-hosting inside the EU or UK can keep personal data under GDPR overview rules. For card data, see PCI-DSS basics to keep agents out of scope or in a reduced scope segment.
Latency is the next reason. Fraud agents need sub-second paths to score or hold risky events. Each network hop adds jitter. When your agent sits near your transaction switch or risk microservices, you remove two to three public network trips. That can be the difference between a clean approve and a chargeback spike.
Cost also pushes teams to self-host. Per the BKO, the core framework can be free, and a small VPS can cost about $5/month, with total under $10/month when you add modest model calls. At scale, steady workloads make reserved compute and on-prem GPUs more cost-efficient than pay-per-token APIs. However, don’t chase pennies and forget controls. You pay for weak audit trails in the next exam.
When to use cloud vs. self-hosting
So, when is cloud fine? For non-sensitive use cases, such as agent-based customer help on sanitized data, a managed model API can be fine. When the agent sees live PAN, trading orders, or AML narratives, self-hosting is the safer path. Financial institutions embracing AI for fraud detection are landing on a hybrid: keep the agent, tools, and routing in your VPC, and swap model backends per data class.
-
When cloud-hosted is fine:
-
Sanitized chat for FAQs, no PII or PAN.
-
Offline scoring of de-identified data.
-
Early prototyping with fake data.
-
When self-hosting is essential:
-
Real-time fraud checks on live transactions.
-
Agents that write to ledgers, CRMs, or payment rails.
-
Any flow with PCI-DSS or GDPR-regulated data.
“Security-focused setup including access control and encrypted communication should be present from day one.” — Internal security guideline
Also Read!
OpenClaw vs AutoGen for Fintech: Which Is Better for Self-Hosted AI Agent Deployment?
How to Set Up a WhatsApp AI Automation Bot for Your Ecommerce Store
Step-by-Step: Deploying a Self-Hosted AI Agent for Financial Workflows
If you follow this sequence, your self-hosted ai agent deployment will clear basic reviews and scale without rewrites.
- Choose infrastructure (VPS vs. bare metal vs.
-
VPS: Fast to start. Pick a provider that offers private networking, IPv6, and customer-managed keys. Map to a $5/month tier for a sandbox; scale in the same family later.
-
Bare metal: Good for high and steady load, or model fine-tuning. You control NICs, disks, and firmware. – On‑prem: Best for strict data residency or air‑gapped environments.
-
OS: Ubuntu 22.
-
Runtime: Docker 24+ or containerd, Kubernetes optional
-
CPU: x86_64 with AES‑NI and AVX2
-
Disk: NVMe SSD, encrypted with dm-crypt/LUKS
-
TLS: 1.
- Select an agent framework
-
Pick a framework that supports tool calling, function routing, and graph-style control flow.
-
LangGraph for deterministic, node-based workflows. – AutoGen for multi-agent patterns with clear role split.
-
CrewAI for team-of-agents with task planning. – Ensure you can stub tools for tests and run headless in CI. If you need a managed path later, keep an adapter that swaps runtimes without code churn.
- Configure encryption and RBAC
-
Network: Enforce TLS 1.3 in and out. Pin service certs where possible. – At rest: Encrypt volumes with strong keys. Rotate keys on a fixed schedule.
-
RBAC: Use an IdP (SAML/OIDC). Define roles like reader, operator, auditor, and owner. Bind service accounts to least-privilege policies. – Secrets: Store in a KMS or sealed vault.
Never hardcode API keys. Add short TTLs and automated rotation. – Audit: Log who ran which tool, on what data, and to what effect. Keep tamper-evident logs.
- Integrate with core banking/CRM APIs
- Build typed clients for key systems: core ledger, payments switch, AML case manager, and CRM. – Add rate limits and retries with jitter. Mark idempotency keys for writes. – Set a data contract.
Redact PII before it leaves the secure segment. For analytics and BI, route through a read-only view or feature store. – Plan “break glass” paths. If the agent stalls, your API should degrade to a safe default.
- Set up monitoring and alerting
- Metrics: Track latency (p50/p95), error rates, token spend (if any), and tool success ratios. – Tracing: Propagate a trace ID through the agent, tools, and downstream calls. – Alerts: Page on SLO breaches and abnormal decision rates.
Suppress flapping with short windows. – AI/ML pipeline development: Keep your data prep, feature jobs, and model registry in version control. Reproducible runs matter in audits.
- Test under load and inject failure
-
Load: Rehearse peak events. Use historical traffic patterns to set RPS and concurrency. Run in staging that mirrors prod. – Scenarios: Concurrent sessions that match your active user base, and back‑to‑back tool calls.
-
Failure: Drop a dependency, slow a DB, and rotate keys mid-run. Confirm graceful degradation. – Verification: Use an expressive assertion engine to check outcomes, and include run-comparison tooling to track changes across builds.
Moreover, keep total cost in sight. The BKO notes a free core framework and a small VPS around $5/month, with total usually under $10/month when model calls are light. That lets you run a real sandbox without a purchase order.
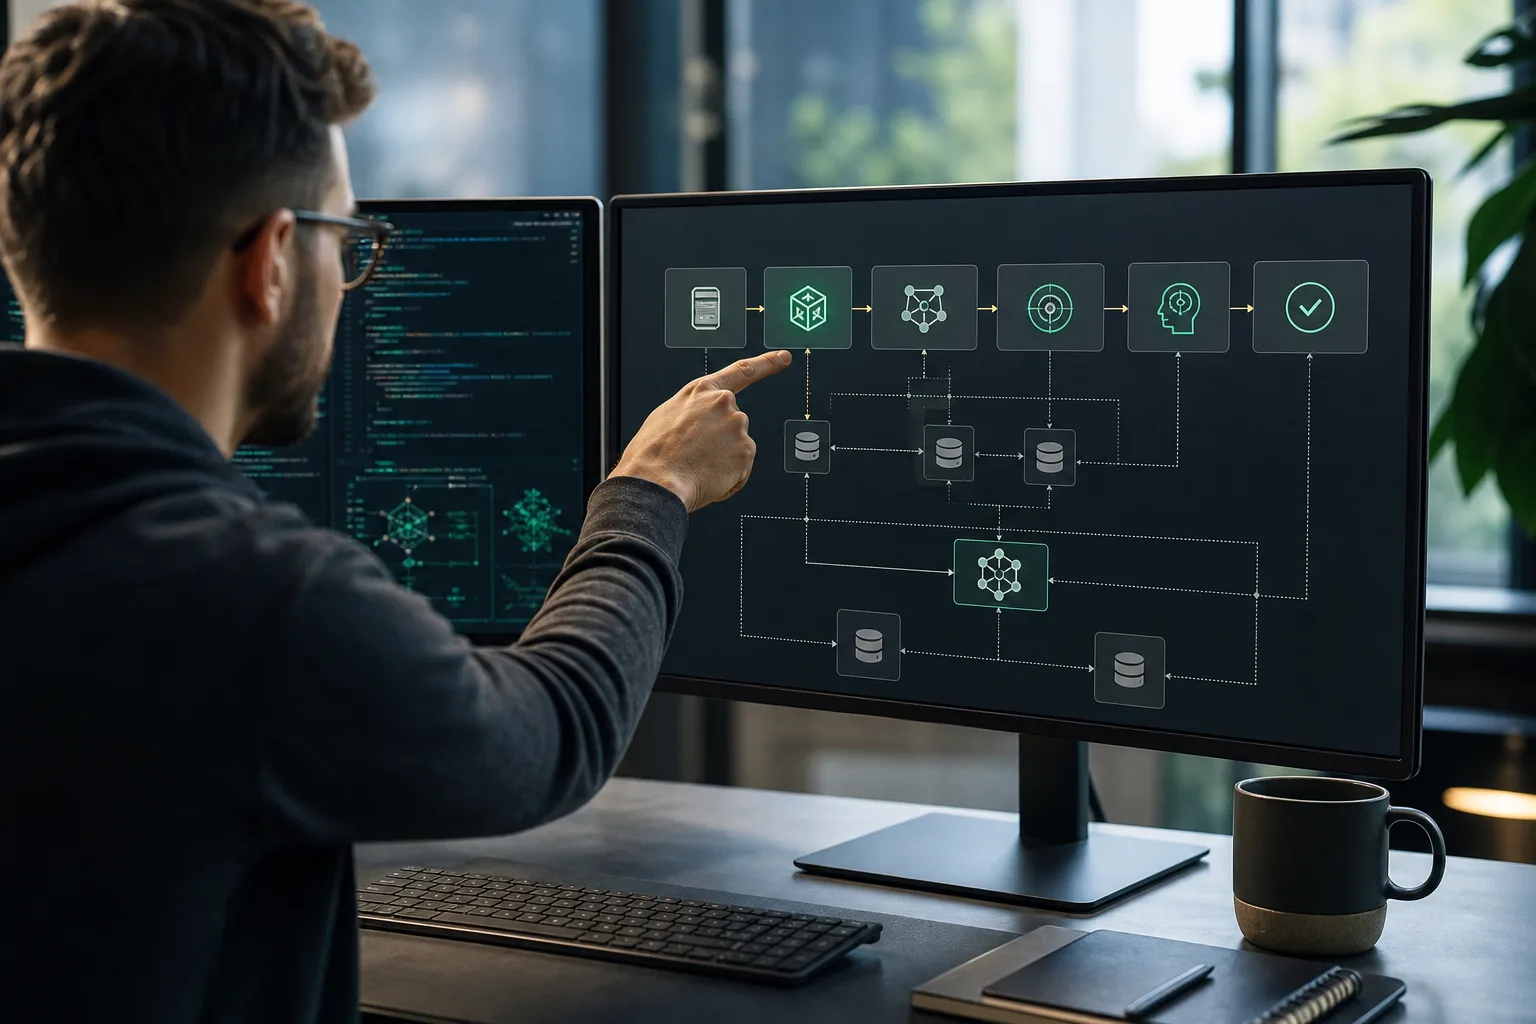 , system integration, monitoring/alerting, load testing and failure injection; clean fintech styling; icons for bank core, CRM, and audit logs)
Integration tips for CRMs and analytics tools
- Use webhooks or event buses to pass agent outcomes into your CRM.
- Send anonymized metrics to analytics. Keep PII out of dashboards.
- Add feature flags so product can turn agent actions on/off per segment.
What “high-volume” looks like in practice
- Plan for bursts that reflect fraud spikes after major events.
- Cache hot features to cut repeated reads.
- Batch non-critical writes when queues back up.
5 Mistakes Fintech Teams Make When Self-Hosting AI Agents
First, skipping environment parity between staging and prod. If Docker images, secrets, or model versions differ, your tests lie. Environmental parity for consistent test results is worth the setup time. Mirror infra, seed synthetic data that matches shape and edge cases, and run the same IaC in both places.
Second, ignoring audit logging requirements. Auditors ask who, what, when, and why. If your agent mutates data, you need a signed, immutable trail. Include tool inputs and outputs, link to the original trace ID, and store hashes for payloads so you can prove they were not changed. Tie log retention to your policy.
Third, hardcoding API keys. It still happens. A rotated key breaks your job at 2 a.m., or a leaked repo puts you in incident response. Secrets belong in a vault with short TTLs and a rotation job. Build the renewal flow from day one, and test it monthly.
Failover and graceful degradation
Fourth, no failover or graceful degradation plan. Agents can and will stall. Without a fallback, you block checkouts or hold payouts.
Design the agent as an add-on: if it times out, default to a safe path. For fraud, that might be a rules-only score; for support, that could be a human queue. Runs autonomous workflows on a self-hosted server should not mean “no human safety net.
Fifth, treating the agent like a chatbot. Your risk and ops flows need tools, memory, and routing, an autonomous workflow, not a single prompt. Map each task to tools with strict schemas.
Split read and write powers. Then plan for growth. Scalability planning for long-term growth means sharding workloads, isolating tenants, and keeping infra-as-code tidy so you can add regions and zones.
“Test case structuring in a hierarchical manner cut our debug time to hours, not days.” — Platform engineering note
Also Read!
OpenClaw vs Wati for Ecommerce: Which Is Better for WhatsApp AI Automation?
How to Set Up a WhatsApp AI Automation Bot for Your Fintech Company
Frameworks and Tools for Self-Hosted Fintech AI Agents
You have solid open-source choices.
LangGraph shines for graph-style flows where you want each node to call tools and pass control with clear edges. AutoGen makes it simple to define “specialist” agents (risk, KYC, payout) that talk to each other. CrewAI focuses on team coordination and task plans with handoffs. Any of the three can serve a fintech workload if you add strict tool schemas, retries, and good logging.
For orchestration at scale, multi-agent design helps. You can split duties: one agent reads transactions and features, one scores risk, one explains a decision for audit, and one writes outcomes to CRM. That pattern fits the “Multi-Agent Orchestration” you will see in managed offerings. Model training and fine-tuning on domain-specific data is useful for reasons you know: chargeback narratives, merchant categories, and local slang change the meaning of the same words across regions.
Tools like GlobussoftAI’s OpenClaw are one option if you want managed deployment, custom multi-agent designing and deployment, and professional deployment and installation layered on top of an open-source AI agent framework. The BKO notes “Over 1,000 hours of testing data was used to explore OpenClaw’s capabilities” and “Reached 100,000 GitHub stars in under eight weeks,” which speaks to social proof. If you prefer to stay DIY, keep reading their OpenClaw benefits on GitHub style notes for ideas you can port into your stack.
On models, you can go local or API-based:
- Local LLMs keep tokens in your VPC. Good for strict data rules and steady load. You need GPUs and MLOps. – API models give fast starts and fresh weights.
Good for sandboxes and non-sensitive tasks. Use anonymization and redaction tools on the client side. – Hybrid: Route sensitive prompts to local, send low-risk tasks to an API. Keep the agent runtime neutral so you can swap endpoints.
Furthermore, add classic ML where it makes sense. Gradient-boosted trees over a feature store still win a lot of fraud tasks. Your agent can call a local model for risk and use an LLM to explain outcomes in plain words for case agents and auditors.
If you want examples of where agents fit in wider ops, this guide on AI agent solutions for business automation shows common patterns you can adapt to fintech.
What to Do Next: Your First 7 Days
Day 1: Audit current data flows. List every place the agent will read or write. Mark data classes (PAN, PII, trade, internal). Note which flows need sub-second latency. Sketch the boundary for PCI-DSS and GDPR so you know where the agent can live.
Day 2: Spin up a sandbox VPS in a private network. Use Ubuntu 22.04 LTS, Docker 24+, and TLS 1.3 at the edge. Set up your secret store and roles. Add a CI pipeline that builds the same image for staging and prod to keep environmental parity.
Day 3: Pick a single-purpose agent. A great start is transaction anomaly alerts. Scope: read a recent transaction stream, score risk with a simple model, send an alert into your CRM, and log an audit trail. Keep write powers off on day three.
Days 4–7
Day 4: Wire tools. Add typed clients for the transaction API and CRM. Add redaction for PII in logs. Enforce RBAC for tool calls. Add run-comparison tooling so you can diff outcomes across builds.
Day 5: Measure latency and accuracy. Track p50/p95 end-to-end, tool times, and alert time to CRM. For accuracy, create a labeled set of known fraud and safe cases. Performance optimization now is about fixing slow tools, not tuning the model.
Day 6: Inject failure. Drop the CRM, slow the DB, rotate a key. Confirm the agent times out and your system degrades with a safe default. Capture clean alerts and traces.
Day 7: Iterate. Turn on writes only for a small, low-risk slice. Hold a review with security and risk. Plan week two: expand features, tune thresholds, or add a second agent for AML notes.
For deeper background on agent frameworks you can adapt beyond fintech, skim this practical read for small teams: Best setups for SMBs in 2026. The lessons carry over to larger stacks.
Moreover, keep your eye on security. End-to-end encryption and role-based access controls, with clear audit logs, will save you hours in each review cycle. The upside is real: per the BKO, businesses that add AI services report up to 40% lower operational costs and a 30% rise in productivity once they stabilize their pipelines.
For privacy law refreshers, bookmark GDPR’s scope and lawful basis notes in the GDPR page above. For stream scoring ideas, you can scan a live-inference pattern paper on arXiv and translate it into your risk graph without picking a vendor today.
Key Takeaways
- Keep the agent, tools, and routing inside your network; choose local vs. API models per data class, and plan hybrid from day one.
- Build security in first: end-to-end encryption, RBAC with least privilege, KMS-managed secrets, and tamper-evident audit logs.
- Make self-hosted ai agent deployment boring to run: same images in staging and prod, typed clients, and clear SLIs and SLOs.
- Prove it under stress: concurrency that mirrors peaks, failure injection, and graceful fallbacks to safe defaults.
- Start small: one agent for anomaly alerts, measure p95 latency and accuracy, then expand to payouts, AML notes, or CRM writes.
What to Do This Week
Pick your infra, choose a framework, and ship a single-purpose agent behind a feature flag. Lock it down with RBAC and encryption, wire it to your CRM, and run load plus failure drills. Then review logs and traces with risk and security, and decide if you widen the slice or add a second step in the workflow. With that, your self-hosted ai agent deployment moves from plan to proof, without tripping audits in 2026.