Businesses implementing AI services report up to a 40% reduction in operational costs and 30% increase in productivity. If you’re asking how a vector database does work, here’s the short answer: it stores math-friendly “fingerprints” of your data (embeddings) and finds the most similar items fast.
In practice, a vector database helps you search by meaning, not just exact words. You turn text, images, audio, or code into high‑dimensional vectors. Then, you query with another vector to get near matches. As a result, you can power smart chat, recommendations, and fraud checks without writing custom rules for each case.
For 2026, this matters because search and assistants are now context-first. Traditional indexes alone struggle with synonyms, typos, mixed languages, and vague asks. Vectors fix that by mapping related ideas near each other in space. You still keep your main database for transactions and reports. You add a vector store to answer “find me things like this” at scale.
 → embedding model → vector index (HNSW/IVF) → query vector → nearest neighbors returned; muted palette; labels for cosine similarity and metadata filters)
What Is a Vector Database, and Why Should You Care?
Think of two ways to organize music. Libraries shelve albums by strict fields: artist, year, genre. Playlists group songs that feel alike: same mood, tempo, or vibe. A vector database is the playlist approach for all kinds of data. It groups items by meaning, so “physician” ends up near “doctor,” and a photo of a golden retriever sits near “dog at the park.
Here’s how that works in plain terms. First, you pass each item through a model that creates an embedding, a long list of numbers. Each list is a point in high‑dimensional space. Two points that sit close together mean the items are similar. Distance can be measured in several ways; cosine similarity is common because it focuses on direction over scale.
Now, compare this to a relational or NoSQL database. Your SQL database is great at “find invoice 8429” or “sum sales by region.” Your document store is great at flexible schemas and fast key lookups. However, both struggle with “find products that feel like this one.” That’s where vector search shines. It’s built for nearest neighbor lookups in spaces where “closeness” equals “related.
Moreover, the index is different. Instead of B‑trees or hash maps, vector databases use approximate nearest neighbor (ANN) structures that skip most of the space yet still find strong matches fast. That’s key once you have millions of vectors.
Library vs. Playlist: A Concrete Contrast
- Relational/NoSQL: exact match, filters, joins, aggregates; precise and auditable.
- Vector DB: similarity search, fuzzy match, semantic recall; flexible and human-like.
- Best practice: use both. Keep facts in rows or docs; add vectors for meaning.
- Typical blend: filter by metadata first, then rank the survivors by vector distance.
Finally, why should you care? Because users don’t speak in strict fields. They ask in their own words. Vectors meet them where they are. And yes, a vector database does work side‑by‑side with your current stack, not in place of it.
How Vector Databases Work: A Step-by-Step Breakdown
At a high level, the flow is simple: embed, index, query, return. The details matter, though, because speed and recall hinge on the right choices.
First, you convert raw data to embeddings. A small model might produce 384‑dimensional vectors; a larger one might output 1,536 or more. Higher dimensions can capture richer nuance but increase memory and index time. Second, you build an ANN index.
Popular options include HNSW graphs (see the original HNSW paper on arXiv) and IVF (inverted file) lists. Third, you turn your user’s ask into a query vector. Fourth, you search for the nearest neighbors and return the top‑k items, often with a rerank step.
The Pipeline at a Glance
- Data → Embeddings
- Text: chunk documents into 200–1,000 tokens.
- Images/audio/code: use a model trained for that type.
- Embeddings → ANN Index
- HNSW: builds a multi-layer graph for fast greedy search.
- IVF: clusters vectors, then probes a few clusters for speed.
- Query → Query Vector
- The same embedding model turns the query into a vector.
- Use the same preprocessing you used for the indexed data.
- Vector Search → Nearest Neighbors
- Retrieve top‑k by distance, e.g., cosine or Euclidean.
- Optionally rerank with a stronger model for precision.
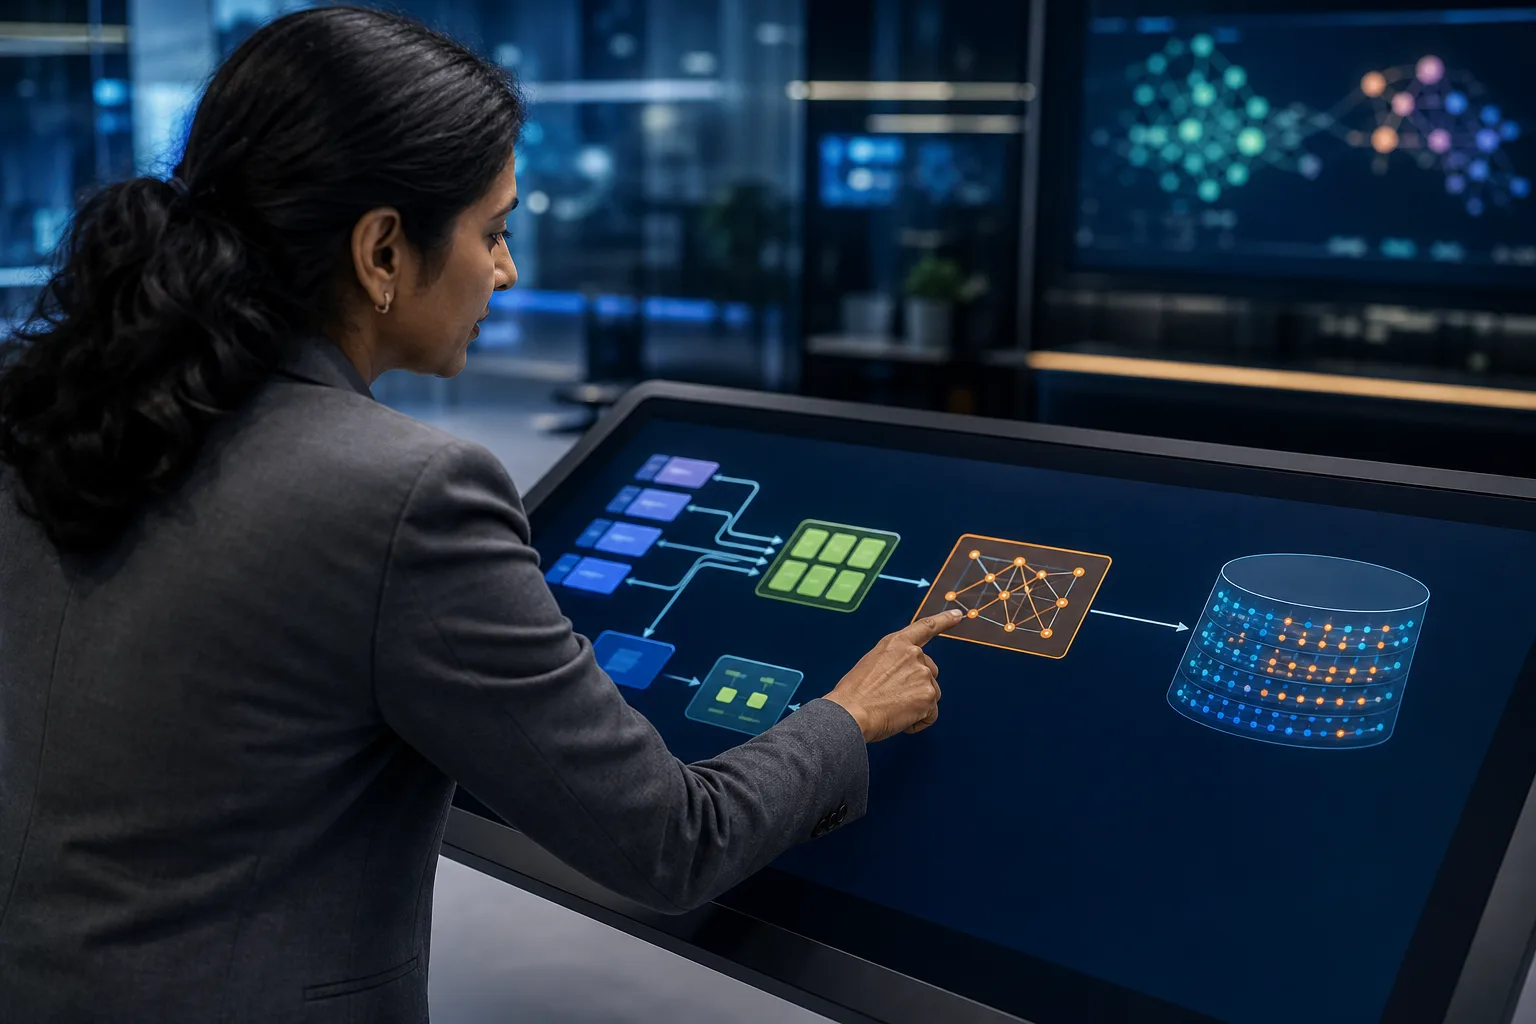 , query vector, nearest neighbors; include small callouts for metadata filters and cosine distance)
Furthermore, good systems blend metadata filters with vector math. You filter candidates first (e.g., “only 2024–2026 invoices in Europe”), then run ANN within that slice. This keeps results relevant. It also keeps cost in check by shrinking the search space.
For recall and speed, you tune index params. HNSW has “M” (graph degree) and “ef” (search breadth). IVF has the number of lists and probes.
There’s no single best pick; your data shape and latency needs decide. If you want a deeper primer, the Nearest neighbor search article covers exact vs. approximate methods and trade‑offs.
Therefore, when you hear “a vector database does work like magic,” the magic is math plus indexes. The model puts meaning into numbers. The index finds close points quickly. The query rides both.
Start a free proof-of-concept →
Also Read!
Why AI Transformation Is a Problem of Governance (And How to Fix It)
Common Misconceptions About Vector Databases
First, “Vectors replace my database.” They don’t. You still need your system of record for transactions, audit trails, and reports. Vectors add semantic recall. On the other hand, trying to cram all storage into a vector DB leads to pain: high memory use, slow writes, and tricky consistency.
Second, “A vector DB is a search engine.” Not quite. It’s one engine for similarity. You still need text indexes, filters, and at times a rerank model. In fact, the strongest systems pair keyword and vector search. You catch both exact matches and “close in meaning” hits.
Third, “Higher dimensions are always better.” Past a point, you hit the curse of dimensionality: distances blur, indexes bloat, and recall gains fade. As a result, a 768‑dimensional model might outperform a 1,536‑dimensional one for your task once you weigh speed, RAM, and cost.
Myths To Watch For
- “All vector databases perform the same.” Index choices, metadata filters, and write paths differ a lot.
- “ANN is approximate, so quality is random.” With tuned params and rerank, you get stable, high recall.
- “No need for metadata.” Without filters, you return near matches that are wrong by time, region, or policy.
- “Bigger k is safer.” Returning 200 neighbors balloons cost and adds noise; start with 10–20 and test.
Finally, people skip evaluation. You need a small, labeled set of queries and “gold” answers. Then, you measure recall@k and latency across settings. Therefore, before you scale, run bake‑offs with HNSW vs.
IVF, 384 vs. 768 dimensions, and different chunk sizes. That is how a vector database does work well in production, you test, then tune.
Popular Vector Database Tools and Where They Fit
You have two broad choices: managed services that abstract the ops, and self‑hosted or open‑source options that you control. Your pick depends on data rules, team skills, and how fast you need to ship in 2026.
Quick Comparison
| Tool | Hosting Model | Strong Fit | Notable Notes |
|---|---|---|---|
| Pinecone | Managed | Fast start, high SLA | Scales clusters for you |
| Weaviate | Open-source/managed | Hybrid search + modules | Graph + text features |
| Milvus | Open-source/managed | Large-scale ANN | IVF, HNSW, disk indexes |
| Qdrant | Open-source/managed | Production-grade filters | Payload (metadata) focus |
| Chroma | Open-source | Prototyping, local dev | Simple, Python-first |
| pgvector | Extension in Postgres | One DB for all | Great for small/medium sets |
Moreover, you can mix and match. For example, run pgvector for a few million rows near your app. Later, move “long tail” archives to Milvus or Qdrant with disk indexes. In addition, you can keep Weaviate for hybrid keyword+vector search where text relevance matters.
Now, getting from prototype to production takes more than picking a store. You need ingestion jobs, index build plans, filter design, monitoring, and access control. This is where AI deployment services like GlobussoftAI OpenClaw Services can help as one option.
The team focuses on AI/ML pipeline development for scalable deployment, smooth integration services to fit AI solutions into existing systems, and system integration with CRMs and analytics tools. For assurance, OpenClaw includes end-to-end encryption and role-based access controls for security, reached 100,000 GitHub stars in under eight weeks, and had over 1,000 hours of testing data used to explore the framework’s features. Pricing is transparent too: the core framework is free, typical VPS costs around $5/month, and total costs usually under $10/month with AI model usage.
Therefore, you don’t only choose a vector database. You choose how you’ll run it, secure it, and grow it. A managed path speeds you up. A self‑hosted path gives you full control. Either way, write down SLAs for latency, recall, and index freshness before you commit.
Schedule a free consult today →
Key Takeaways and What to Do This Week
 with best-practice callouts for chunking, metadata filters, and evaluation metrics; friendly colors)
- A vector database stores embeddings and finds nearest neighbors; it complements, not replaces, your transactional stores.
- ANN indexes (HNSW, IVF) trade tiny precision for big speed wins; measure recall@k to keep quality high.
- Good results blend metadata filters with vector math; filter first, then rank by distance.
- Start small: 384–768 dimensions, k=10–20, and a labeled eval set to tune.
- Spread usage: recommendations, semantic search, dedupe, and threat or fraud pattern matching.
This week, do one concrete test. Pick a free‑tier vector DB or pgvector. Load 1,000–10,000 items with a compact embedding model.
Then, run five real queries from your users and check the top‑10 results by hand. As you adjust chunk size and index params, note how recall and latency move. That hands‑on run will show you how a vector database does work for your data, right now, in 2026.
Moreover, write down what “good” means for you: target latency (e.g., under 200 ms), top‑k, and recall. Then set up a small dashboard to track these as you add more data. As a result, you’ll ship features that feel smart and stay fast as you scale. Finally, keep one rule close: facts in rows, meaning in vectors. Combine both, and you’ll make search and answers feel natural.